Medallion architecture: bronze, silver, gold
kept in this browser
Edit this pageThree layers of Delta tables with increasing quality. Bronze keeps the raw data, silver cleans and types it, gold aggregates it for the business.
Checked against the Databricks documentation on · history
On this page5
What it is
The medallion architecture organizes the tables of a lakehouse into three layers, each with a different quality guarantee:
| Layer | What it holds | Who reads it |
|---|---|---|
| Bronze | raw data exactly as it arrives from the source, plus technical columns (source file, ingestion timestamp) | pipelines only |
| Silver | validated, typed, deduplicated data, with at least one row per source record, no aggregations | data engineers, data scientists |
| Gold | aggregates and models built for a specific use: dashboards, reports, features | analysts, business users |
It isn’t a platform requirement, just a recommended practice: Databricks proposes it as a reference pattern, and the exam treats it as shared vocabulary.
Why it exists
Writing a “clean” table straight from the source looks like a shortcut, but it’s fragile: if the source schema changes, the pipeline breaks and data stops arriving. With a bronze layer that accepts everything (ideally as STRING or VARIANT), the raw data is safe, and the cleanup logic in silver can be fixed and rerun as many times as needed. Gold, in turn, insulates the business from technical details: if the dedup logic in silver changes, the dashboard keeps reading the same gold table.
How it works
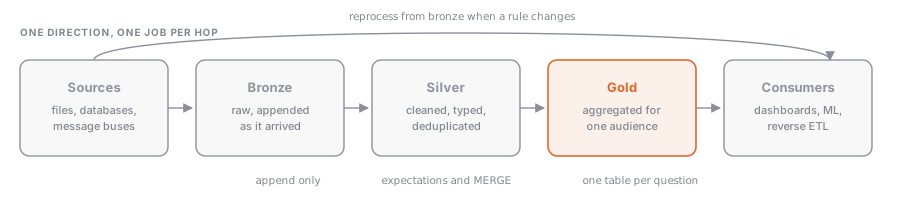 Each step is a batch or incremental transformation between Delta tables registered in Unity Catalog (see Unity Catalog, the governance layer). The typical pattern is one schema per layer (
bronze, silver, gold) inside a catalog per environment.
Bronze: append-only, fed by Auto Loader, COPY INTO, or Lakeflow Connect: managed connectors. You add columns such as _ingested_at and _source_file. Almost nothing gets transformed.
Silver: this is where the cleanup the exam asks about happens:
- handle nulls (
dropnaon keys,fillnaon optional values); - standardize types (
cast,to_date,to_timestamp) and strings (trim,lower); - deduplicate (see Deduplication and aggregations);
- apply quality rules (see Data quality: expectations and constraints).
Gold: aggregations and joins by business domain, often as a materialized view (see Gold objects: tables, views, materialized views, streaming tables).
Writing to silver uses three tools, in order of frequency: saveAsTable / CREATE OR REPLACE TABLE AS SELECT when you rebuild everything, MERGE INTO when you only update the records that changed, and append for purely incremental data.
Example
Bronze holding orders in raw form (every column a string), and silver with correct types.
CREATE OR REPLACE TABLE shop.silver.orders AS
SELECT
  CAST(order_id AS BIGINT)          AS order_id,
  TRIM(LOWER(customer_email))       AS customer_email,
  TO_DATE(order_date, 'yyyy-MM-dd') AS order_date,
  CAST(amount AS DECIMAL(10, 2))    AS amount,
  COALESCE(channel, 'unknown')      AS channel
FROM shop.bronze.orders_raw
WHERE order_id IS NOT NULL
  AND order_date IS NOT NULL;
from pyspark.sql import functions as F
bronze = spark.read.table("shop.bronze.orders_raw")
silver = (
bronze
.dropna(subset=["order_id", "order_date"])
.fillna({"channel": "unknown"})
.select(
F.col("order_id").cast("bigint").alias("order_id"),
F.trim(F.lower("customer_email")).alias("customer_email"),
F.to_date("order_date", "yyyy-MM-dd").alias("order_date"),
F.col("amount").cast("decimal(10,2)").alias("amount"),
F.col("channel"),
)
)
silver.write.mode("overwrite").saveAsTable("shop.silver.orders")When bronze also receives corrections to orders already seen, a full rebuild wastes time. You use MERGE to upsert instead:
MERGE INTO shop.silver.orders AS t
USING (
  SELECT CAST(order_id AS BIGINT) AS order_id,
         CAST(amount AS DECIMAL(10, 2)) AS amount,
         TO_DATE(order_date) AS order_date
  FROM shop.bronze.orders_raw
  WHERE _ingested_at > current_date() - INTERVAL 1 DAY
) AS s
ON t.order_id = s.order_id
WHEN MATCHED THEN UPDATE SET amount = s.amount, order_date = s.order_date
WHEN NOT MATCHED THEN INSERT *;
from delta.tables import DeltaTable
target = DeltaTable.forName(spark, "shop.silver.orders")
(target.alias("t")
.merge(updates.alias("s"), "t.order_id = s.order_id")
.whenMatchedUpdate(set={"amount": "s.amount", "order_date": "s.order_date"})
.whenNotMatchedInsertAll()
.execute())Unlike pandas, dropna and fillna don’t modify the DataFrame in place: they return a new DataFrame, and nothing is computed until you write it out.
Common mistakes
- Casting in bronze: if a value isn’t convertible you lose the raw record, and with
spark.sql.ansi.enabled = true(the default on serverless) the cast fails instead of returningNULL. - Using
mode("overwrite")on a silver table fed incrementally: it wipes out the history. You needMERGEorappend. - Skipping silver and feeding gold straight from bronze: every dashboard redoes the same cleanup, with different results.
- Aggregating in silver: silver should stay at record granularity, so it can serve several different gold tables.
Exam hints
Rewritten from real exam questions: what gets asked and where people slip.
- The exam checks that bronze is the raw landing layer, not the place for business meaning. The common trap is choosing cleansing, business rules, or cross-source aggregation too early. Remember: bronze preserves source data and adds audit metadata such as
ingest_tsor run identifiers; silver cleans, gold aggregates. - The exam checks the medallion architecture order and purpose. The trap is treating Silver as the aggregation layer or judging layers by row count. Remember: Bronze keeps raw data, Silver cleans and conforms it, and Gold serves business-ready aggregates or products.
- The exam checks whether you know the Gold layer is for consumption, not early cleanup. The common trap is to pick a parsing, cleansing, or raw-ingest workload because it sounds useful. Remember: bronze is raw, silver is cleaned and conformed, gold is aggregated or modeled for BI and reporting.
- The exam checks the medallion architecture by asking what changes as data moves from silver to gold. The trap is treating gold as simply more valuable or more true; silver is already cleaned and conformed. Remember: bronze is raw, silver is cleaned, gold is business-ready, often aggregated for analytics.
- The exam checks whether you know Gold is the business-serving end of the medallion pattern, built for analytics rather than faithful capture. The trap is to give it bronze or silver traits: raw history, lineage, or cleaned normalized records. Remember: bronze preserves, silver conforms, gold presents curated aggregates and wide tables for BI.
- The exam checks whether you know what each Medallion layer keeps. A common trap is choosing a refined or business-ready layer, or inventing a separate raw layer. Remember: Bronze is the landing and history layer for raw events; Silver cleans them, and Gold serves business use cases.
Where this sits
- Data Analyst AssociateData Modeling with Databricks SQL
- Data Engineer AssociateData Transformation and Modeling22% of the exam“Implement data cleaning by reading bronze tables with PySpark/SQL, cleaning nulls, standardizing data types, and writing to new silver tables.”
- Data Engineer ProfessionalData Modeling
- Learning pathLakehouse FoundationsHow the Databricks platform is put together: control plane and compute, Delta Lake as the …
- Learning pathData EngineeringBuild production pipelines: ingest with Auto Loader, COPY INTO and Lakeflow Connect, trans…
- Learning pathSQL & AnalyticsQuery the lakehouse from the SQL editor, model gold tables and views for BI, and understan…
Nothing of that kind here yet. Try the full list.